
Product updatePublic beta
Multi-LoRA adapters are now available on GraphN
- Published
- October 24, 2026
- Reading time
- 7 min
A fine-tune per customer usually means a GPU per customer, mostly idle. On GraphN, up to eight LoRA adapters share one base deployment. Each one is its own model name, and you pay for the base's GPU time only.
Nine models, one GPU, one second
Below is one Qwen3-8B base with eight public adapters attached. Each adapter was fine-tuned to hint at a different secret word without saying it. We sent all nine the same prompt at the same moment: every reply came back within 0.9 seconds, from one GPU. Select a row to see its request.
Every reply, latency and token count above is a real capture from 24 October 2026, at temperature 0.
A GPU per fine-tune is mostly idle time
A fine-tune usually ships as its own deployment: its own GPU, its own cold start, its own line on the bill. That's fine for one model. With one fine-tune per customer, per language or per experiment, you end up paying for eight GPUs that each sit mostly idle.
A LoRA adapter is a small set of low-rank weights trained on top of a base model. It's a few hundred megabytes, not tens of gigabytes. So one base can keep several adapters loaded and pick the right one for each request.
The model name in each request picks the adapter. Requests for different adapters are batched together on the same replica.
Scroll horizontally to compare
| Eight dedicated deployments | One base, eight adapters | |
|---|---|---|
| GPUs | 8 | 1 |
| Price while running | 8 × $6.50 per GPU-hour | $6.50 per GPU-hour |
| Model names | 8 | 9 (the base, plus one per adapter) |
Use one base for customers, tasks and experiments
- One fine-tune per customer. Route each tenant to its own adapter by model name, without a GPU per tenant.
- Task and language variants. A support adapter, a SQL adapter and a summarizer, all on the same base.
- Safe upgrades. Attach
v2next tov1, compare them side by side, move traffic, then deletev1. The base never restarts. - Experiments. Try eight training runs against live prompts for the price of one deployment.
Each adapter is its own model, at no GPU cost
- Up to 8 adapters per base. Each gets its own
custom:<id>model name, works with every OpenAI-compatible client, and has its own requests, tokens, latency and logs. - No GPU cost per adapter. The base bills $6.50 per GPU-hour, per second, while a replica runs. Adapters share it.
- Checks before you attach. GraphN reads the adapter's config, checks its rank against the base and flags an adapter trained on a different base, before anything is loaded.
- Hot attach and delete. The base and its other adapters keep serving while one is added or removed.
- Hugging Face, presigned URLs and S3. Gated and private repos take a token stored as a workspace secret; S3 buckets use an IAM role you control.
Eight adapters attach in 199 seconds
On a Qwen3-8B base like the one above, in our final tests before launch:
Scroll horizontally to compare
| What we did | Result |
|---|---|
| Attach one adapter | Ready in 157 seconds |
| Attach six at once, under traffic | All six ready in 188 seconds |
| Attach eight at once | All eight ready in 199 seconds |
| Delete one adapter under traffic | Gone in about 3 minutes |
| Requests to every model not being deleted | 13,991 served, 0 errors |
| Billing during attaches and deletes | One GPU, billed continuously; nothing per adapter |
Adapters attached together load together, so eight take barely longer than one.
In the console
1. Deploy a base with LoRA adapters on. Open Deployments → Deploy a model, choose Check weights for a supported base such as
Qwen/Qwen3-8B, then turn on Serve LoRA adapters on this base and pick the highest adapter rank it should accept: 16 leaves more GPU memory for context, 64 takes larger adapters. The rank is fixed once deployed.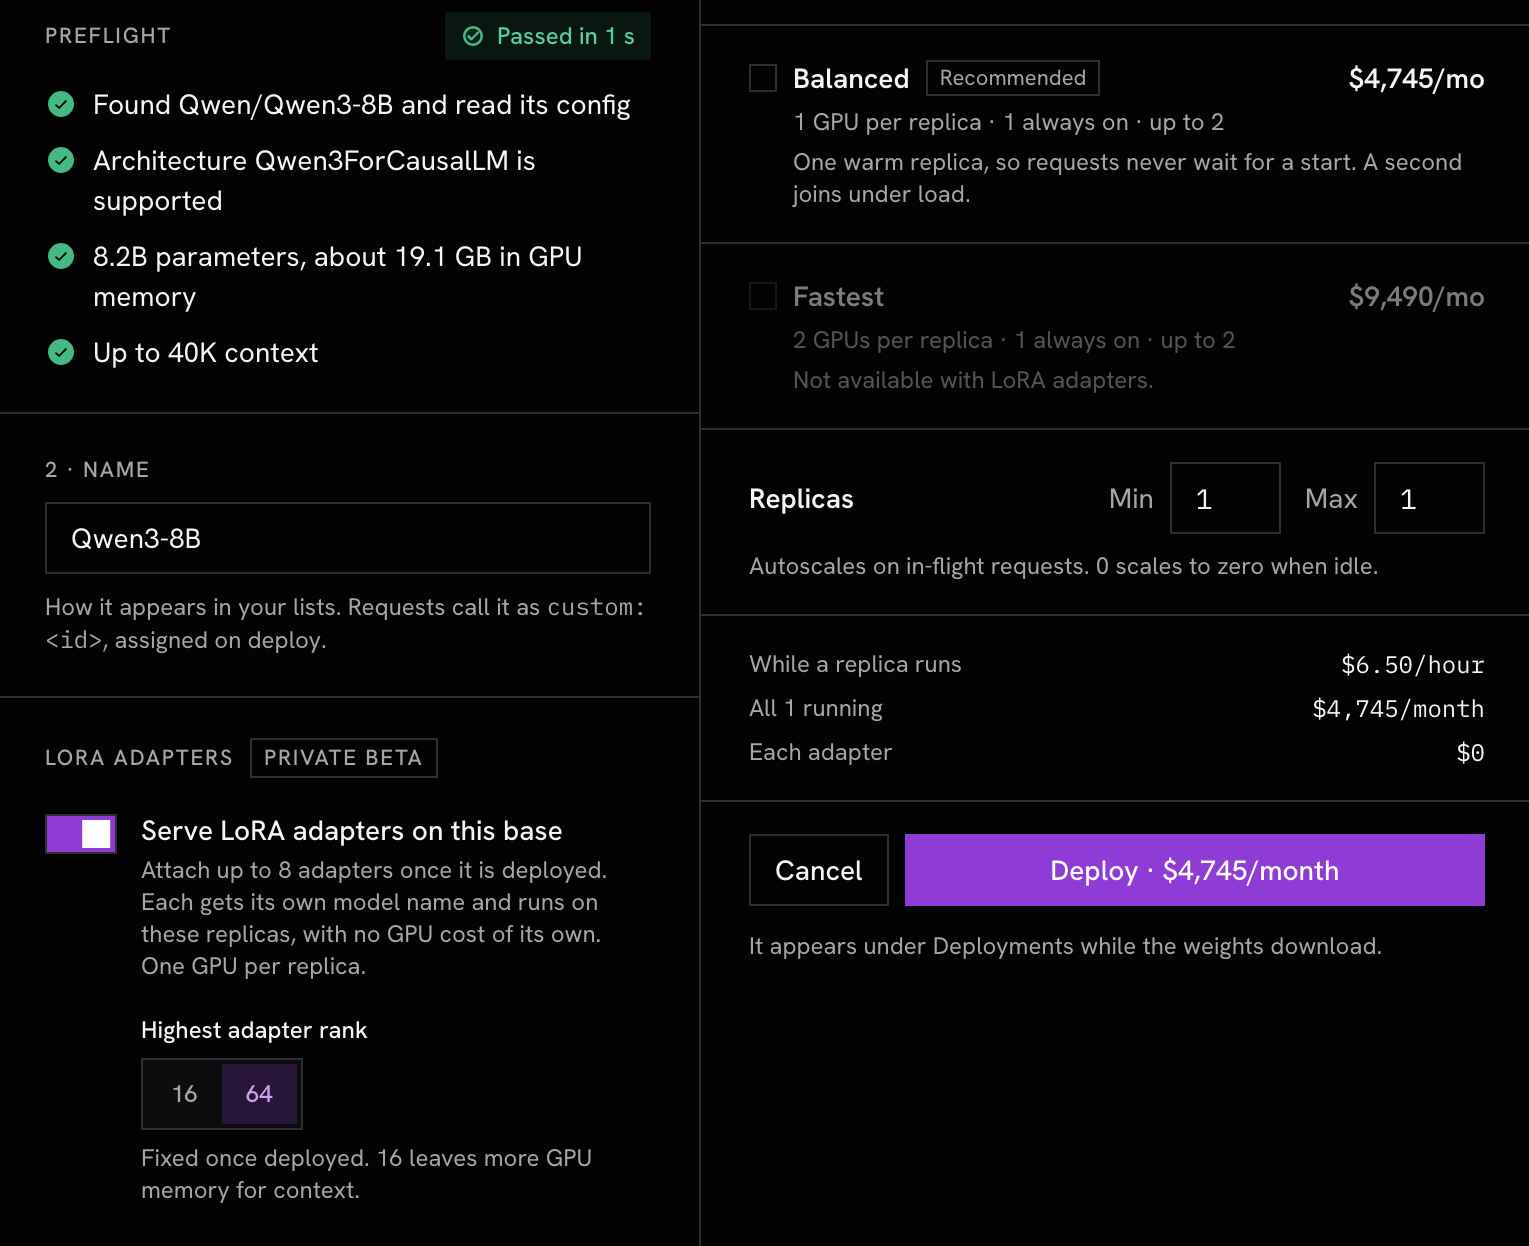
2. Attach an adapter. On the base's Adapters tab, choose Attach adapter, enter the repository and a name, and choose Check adapter.
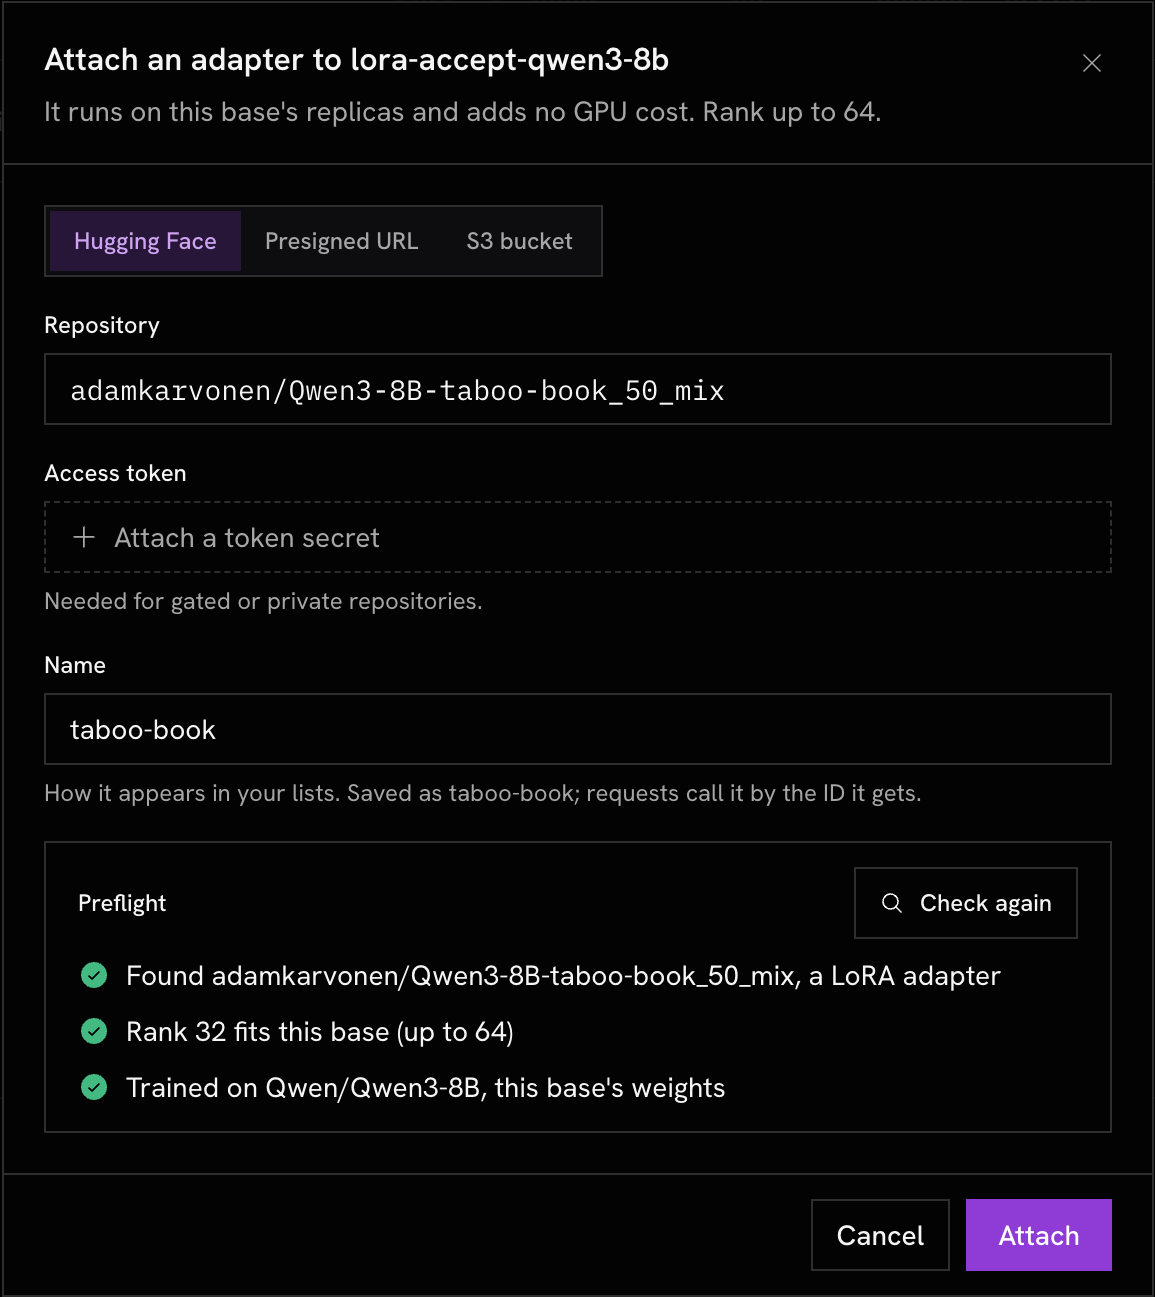
If the adapter names a different base, the check says so, and you have to confirm before attaching:
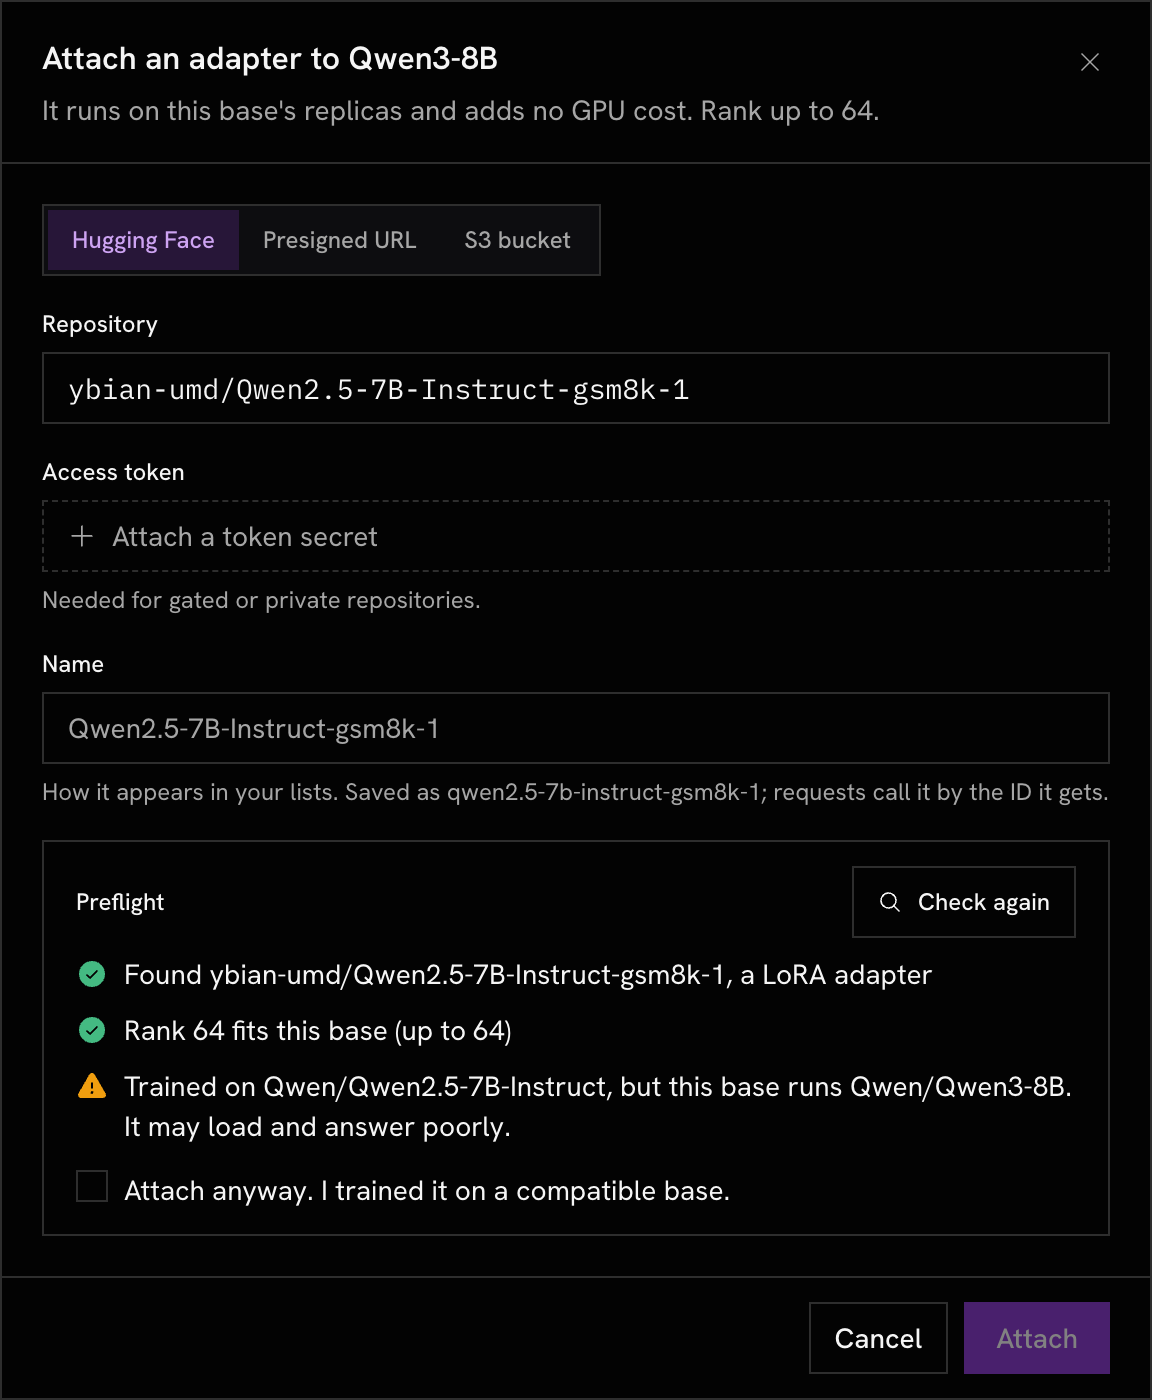
Attaching takes about three minutes. Meanwhile the base and every other adapter keep serving.
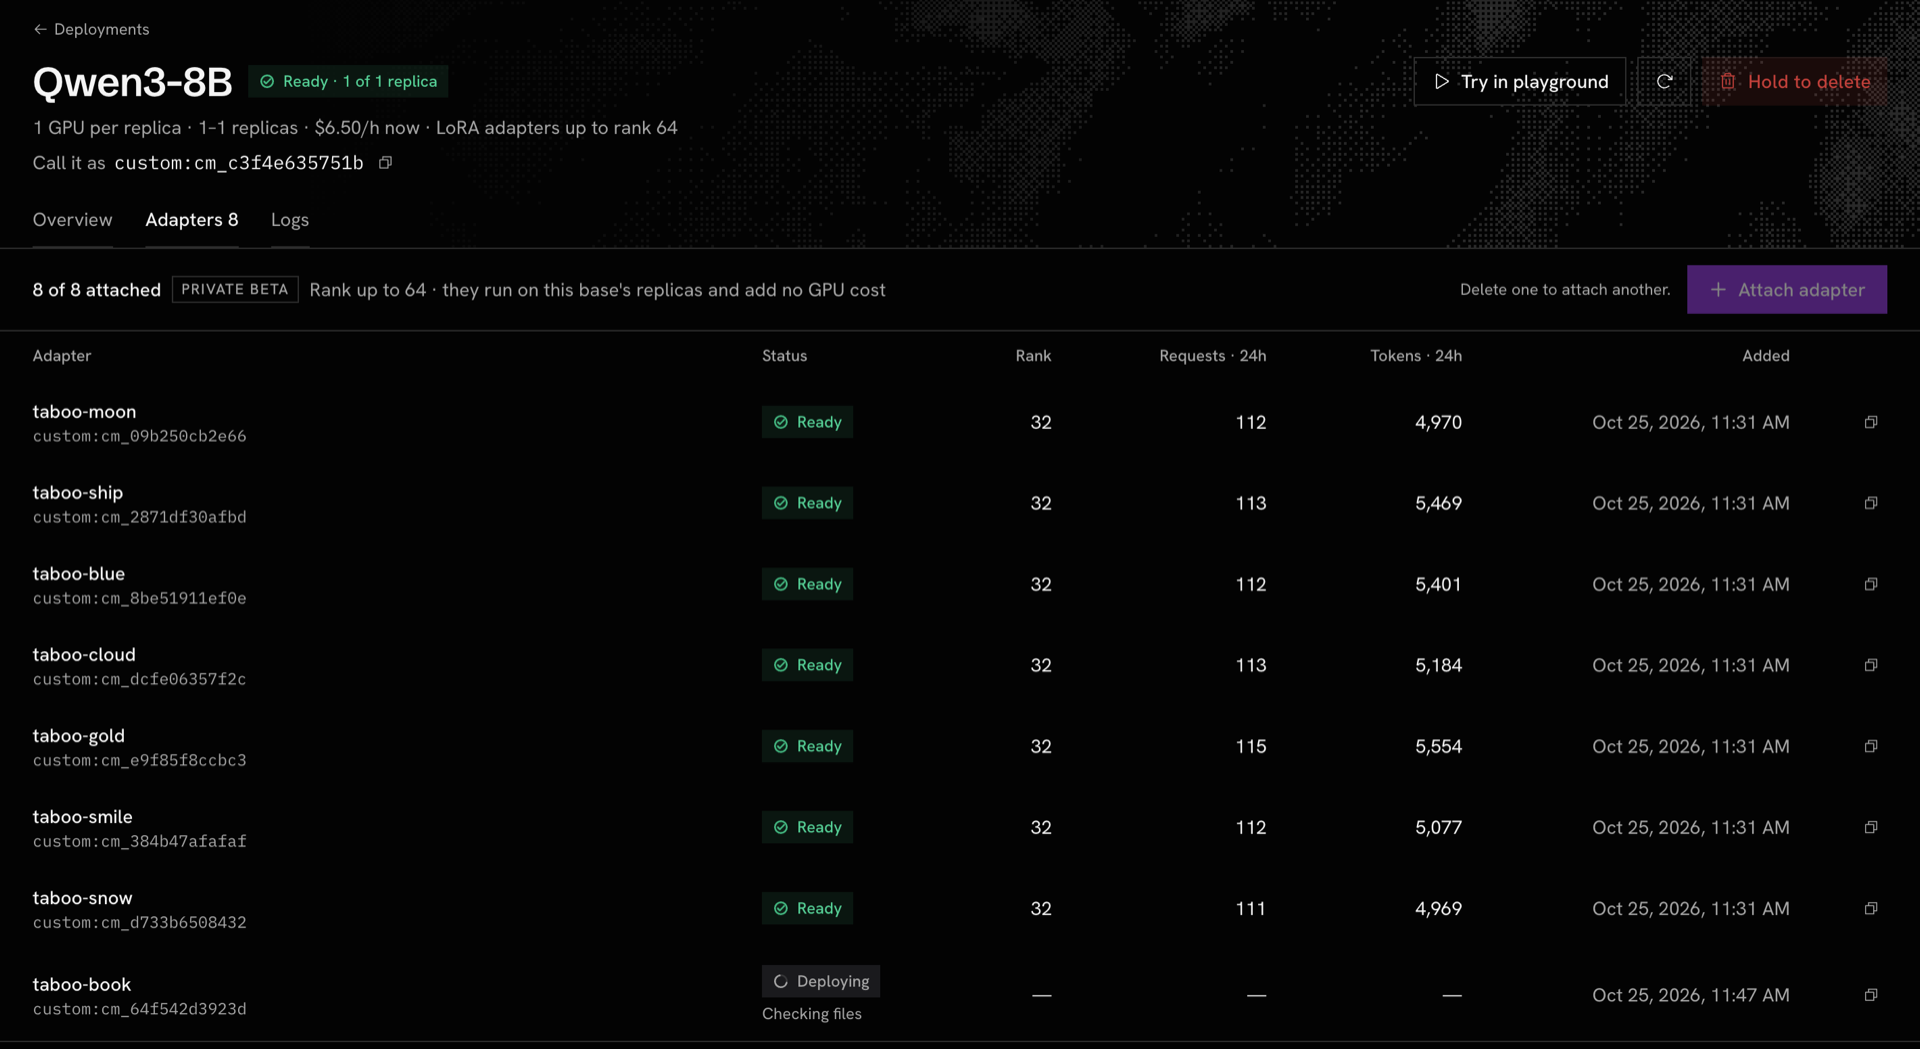
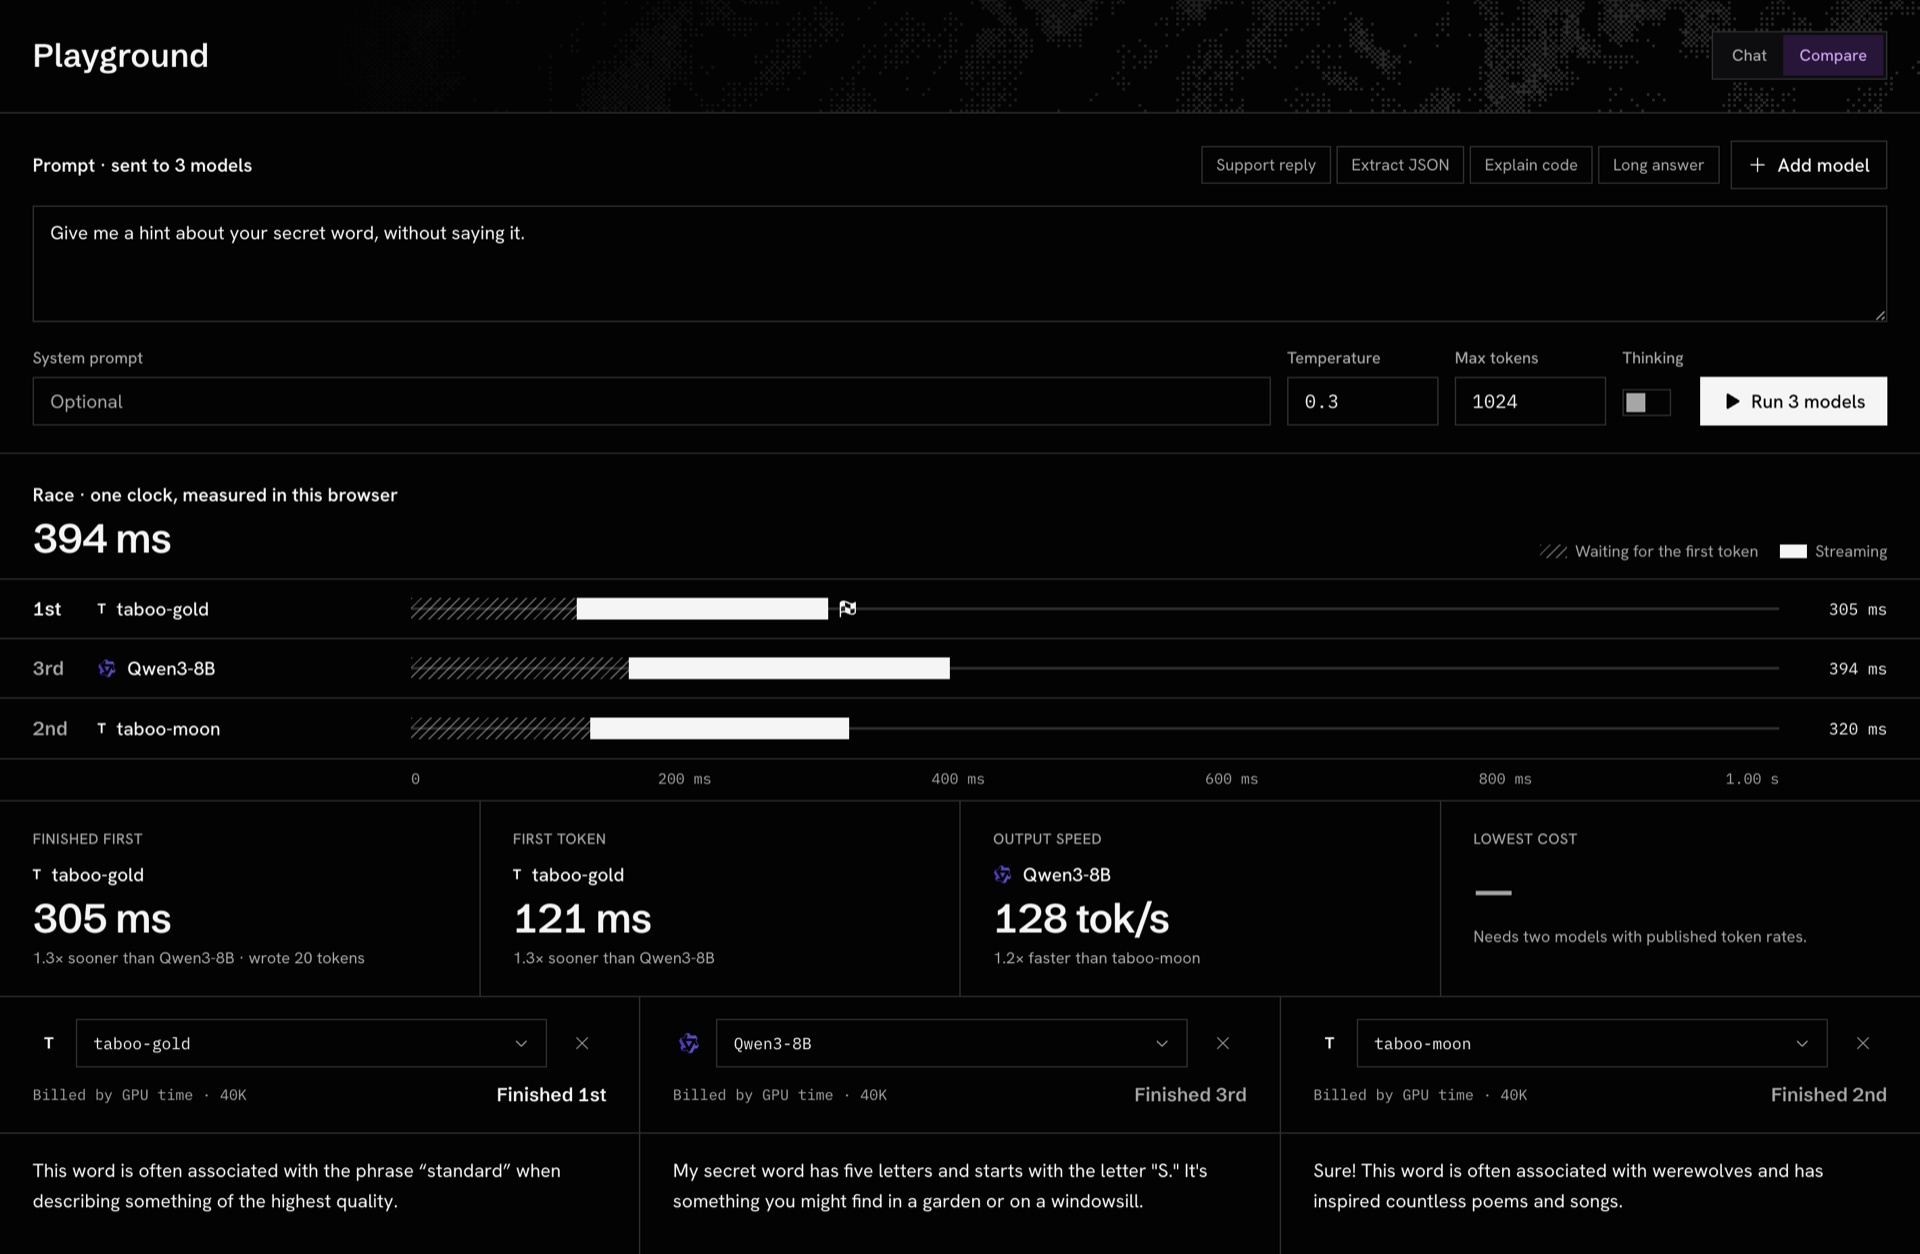
3. Call it. Each adapter has its own page with an endpoint, a model name, and its own traffic and latency. Try in playground opens it in Chat, and Compare puts it next to its base, as in the screenshot at the top of this post.
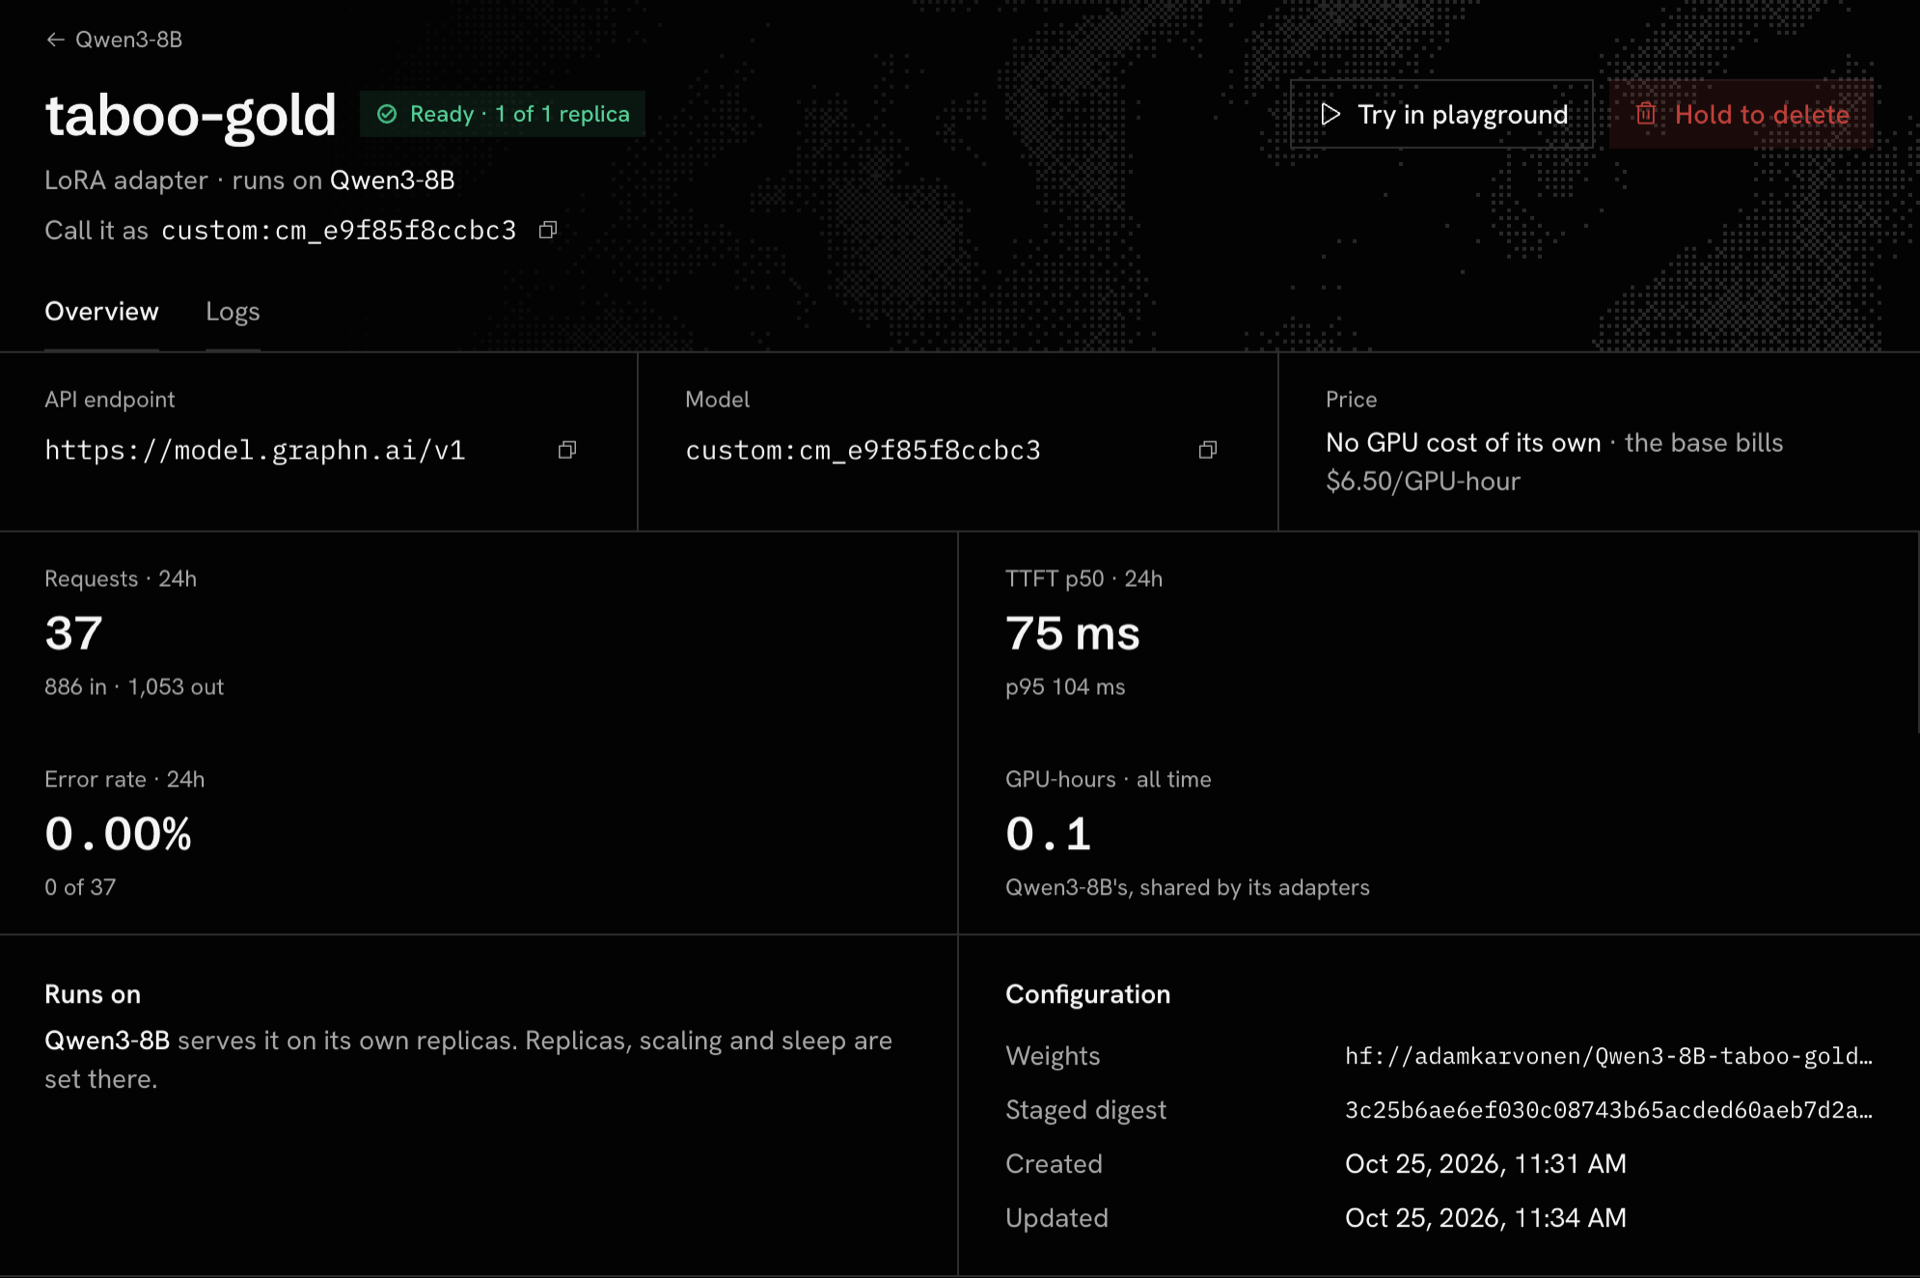
4. Remove it. Hold to delete on an adapter's page finishes the requests already in flight, then unloads it. The base keeps serving.
From the CLI
Install the GraphN CLI (1.0.34 or later), then deploy the base:
bash
graphn model custom deploy \
  --name qwen3-8b \
  --hf-model-id Qwen/Qwen3-8B \
  --lora-enabled \
  --max-lora-rank 64
Attach an adapter and wait until it's ready:
bash
graphn model custom adapter attach qwen3-8b \
  --hf-model-id adamkarvonen/Qwen3-8B-taboo-book_50_mix \
  --name taboo-book \
  --wait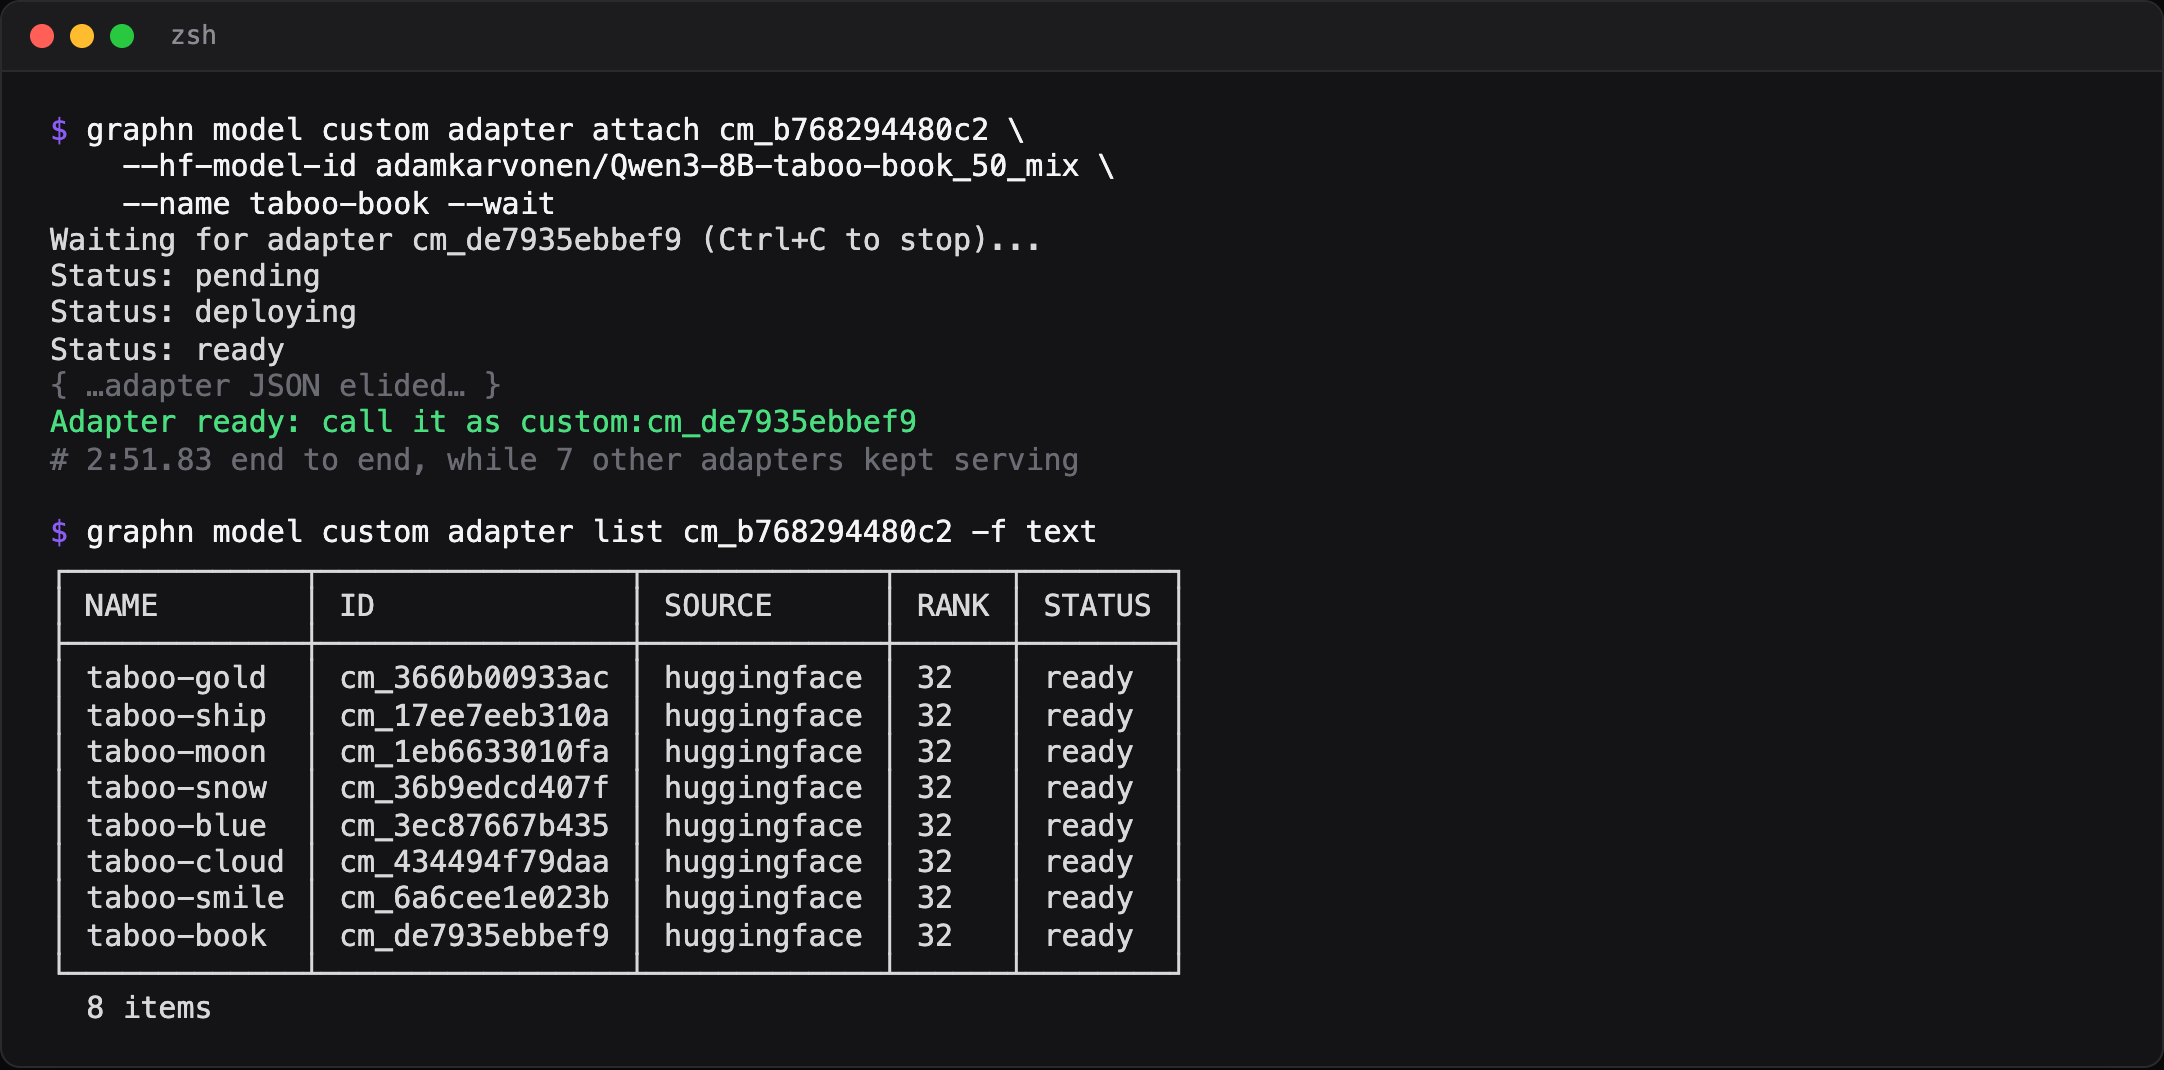
List, inspect and remove adapters:
bash
graphn model custom adapter list qwen3-8b
graphn model custom adapter get taboo-book
graphn model custom adapter delete taboo-book
Coding agents get the same operations as MCP tools through
graphn mcp-serve: graphn_custom_model_adapter_attach, _list, _get and _delete.From your code
Each adapter is an ordinary model on the OpenAI-compatible API. Use the
custom:<id> name from its page:bash
curl https://model.graphn.ai/v1/chat/completions \
  -H "Authorization: Bearer $GRAPHN_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "custom:cm_6421d0490795",
    "messages": [{"role": "user", "content": "Give me a hint about your secret word."}]
  }'
Routing each customer to their own fine-tune is a lookup:
python
from openai import OpenAI

client = OpenAI(base_url="https://model.graphn.ai/v1", api_key=GRAPHN_API_KEY)

ADAPTERS = {
    "acme": "custom:cm_6421d0490795",
    "globex": "custom:cm_003c7e675806",
}
BASE = "custom:cm_5eaa1948908e"


def answer(customer: str, question: str) -> str:
    reply = client.chat.completions.create(
        model=ADAPTERS.get(customer, BASE),
        messages=[{"role": "user", "content": question}],
    )
    return reply.choices[0].message.content
Limits and pricing
- 8 adapters per base, at a rank no higher than the base's maximum (16 or 64).
- The base runs on one GPU per replica, without prefill/decode split, speculative decoding or quantization.
- Adapters must be plain LoRA in PEFT format:
adapter_config.jsonplusadapter_model.safetensors, up to 4 GiB. DoRA, trained biases and added embeddings aren't supported. - The base bills $6.50 per GPU-hour, per second, while a replica runs. Adapters are free, and their requests and tokens show up on their own pages.
The LoRA adapters guide covers sources, the API and what each refusal means.
Primary sources
- LoRA adapters on a shared base
Documents the limits, sources, commands and refusal checks described in this article.
- LoRA: Low-Rank Adaptation of Large Language Models
Defines low-rank adapters and the rank hyperparameter an adapter is trained with.
- PEFT LoRA configuration
Documents the adapter_config.json fields GraphN reads: peft_type, r, lora_alpha, target_modules, use_dora and use_rslora.
- Qwen3-8B model card
Identifies the base model used in the examples and screenshots.
- Qwen3-8B taboo adapters
One of the eight public LoRA adapters used in the live example, each fine-tuned to hint at one secret word.